Triage
Establish impact, urgency and safety before treating the ticket as routine.
A practical guide for IT support staff to identify, test and resolve technical problems without guessing their way into the next incident.
Coming soon · Publication details to follow
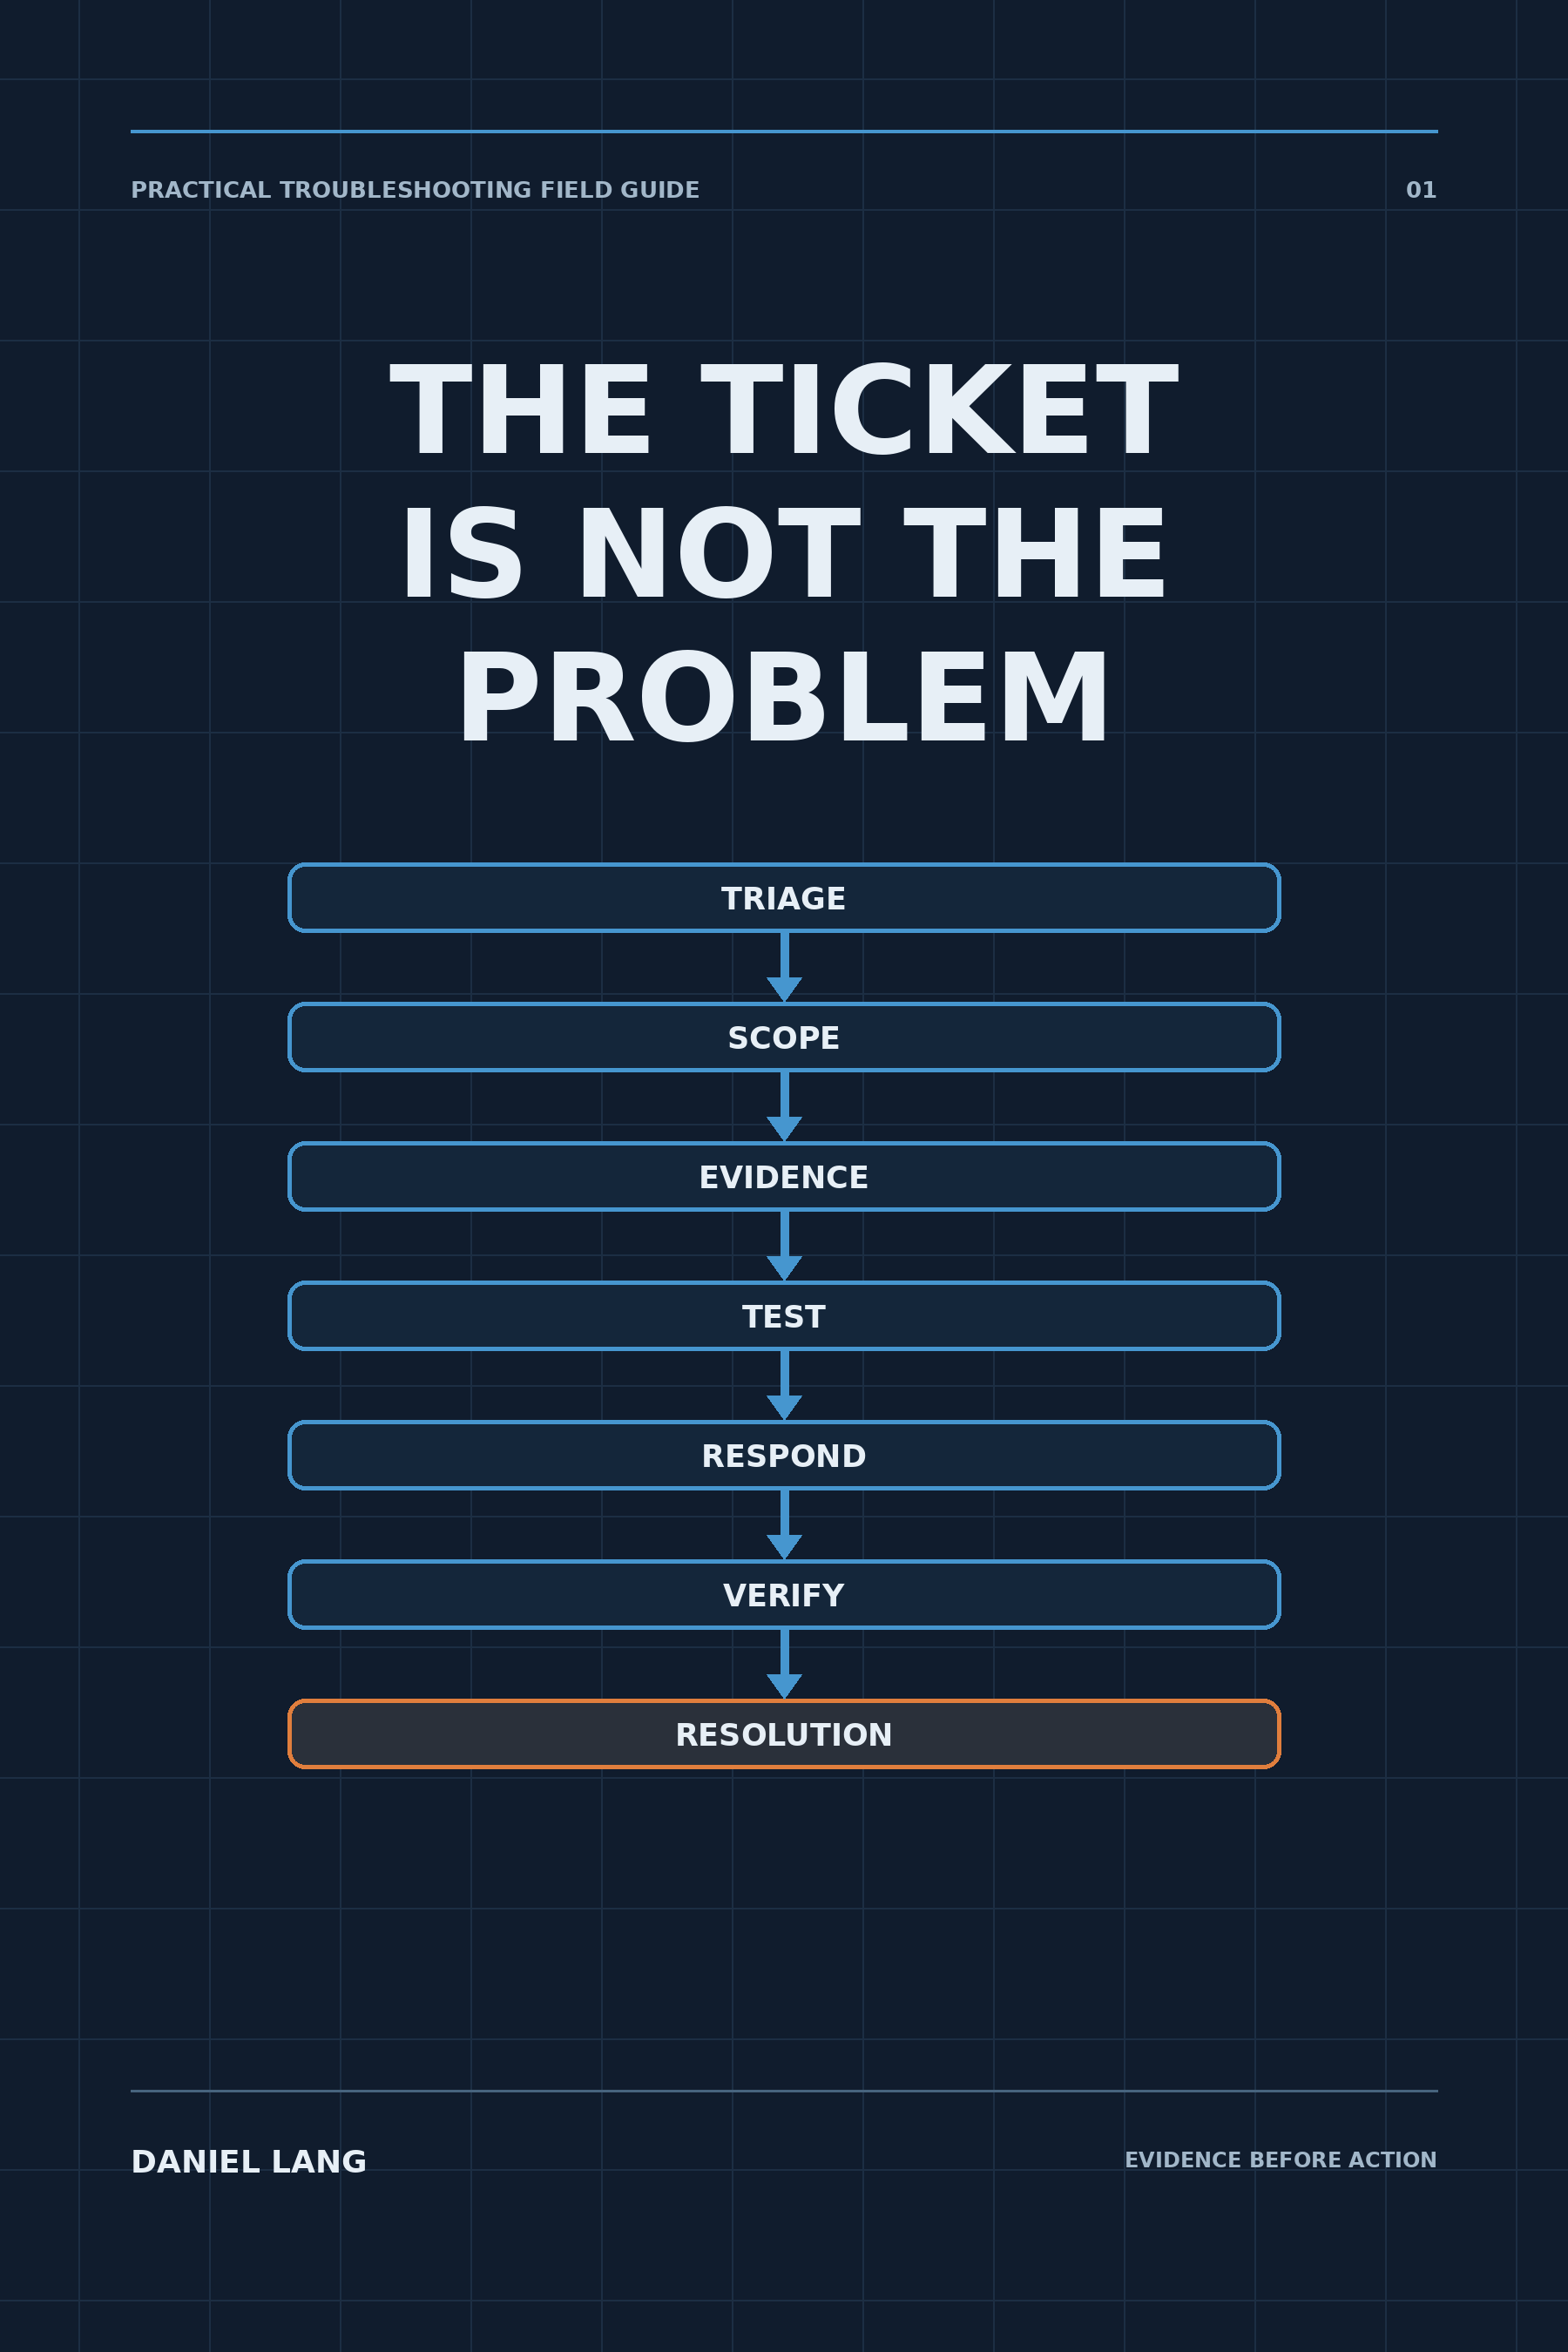
Support work goes wrong when the team starts fixing somebody’s theory instead of investigating the actual symptom. This guide gives junior IT and service-desk staff a repeatable way to establish scope, preserve useful evidence, choose a safe test and know when to escalate.
Not a script to follow blindly. A disciplined starting point for turning a vague report into a testable problem while protecting the user, the system and the evidence.
Establish impact, urgency and safety before treating the ticket as routine.
Find what works, what fails and where the useful boundary sits.
Separate what was reported from what was directly observed or independently verified.
Choose the smallest safe check that can distinguish explanations and change the next step.
Recover deliberately without confusing restored service with a confirmed cause.
Confirm the task works and the access or safety boundary remains correct.
Leave an honest record of the outcome, uncertainty and recurrence follow-up.
The guide uses worked investigations rather than theory-heavy chapters. It shows what an observation establishes, what it does not establish, and how each result changes the next safe action.
Publishing details, a reader sample and Leanpub availability will be announced here soon.